Data augmentation is a way of making a small training set bigger by creating changed copies of the examples an AI model already has. Instead of collecting thousands of extra photos, you flip, crop, rotate, or slightly alter the photos you have, so the model sees each example in several forms and learns what actually matters.
Key Takeaways:
- Data augmentation creates new training examples by changing existing ones, not by collecting new data from scratch.
- It helps models generalize, so they cope better with photos and text they have never seen before.
- Common image techniques include flipping, cropping, rotating, and changing brightness.
- Too much augmentation can hurt, because heavily distorted examples may stop looking like real data.
- It works best alongside good data, careful testing, and other methods such as collecting more real examples when possible.
 What does data augmentation mean in plain English?
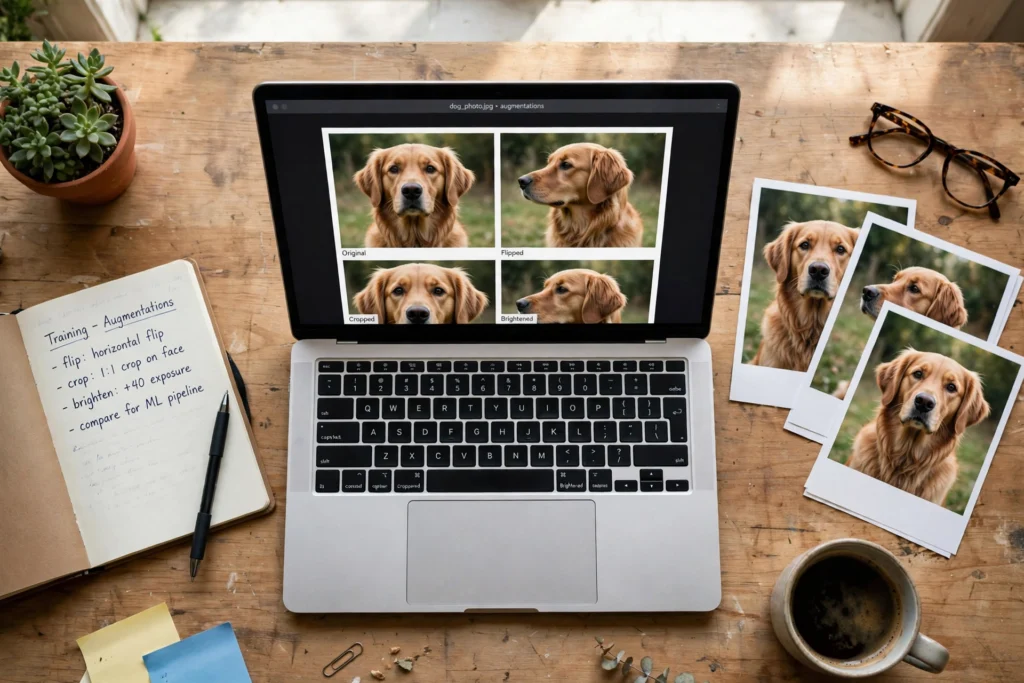
Think of teaching a child to recognize a cat. If you only ever show one photo of one cat, taken from the front in bright light, the child might struggle with a side view, a darker room, or a different breed. Show that same cat from several angles, in different light, and partly cropped, and the lesson sticks much better. Data augmentation does something similar for a model. A photo of a dog can be flipped horizontally to make a second version, cropped a little tighter to make a third, and brightened slightly to make a fourth. The label stays the same — it is still a dog — but the model now has four examples instead of one. Over a whole dataset, those variations add up to a much richer training set.
Why do AI models need more examples?
Machine learning models learn patterns from examples, and they are very good at finding shortcuts. Give a model a small dataset, and it may memorize the exact photos it saw rather than learning the general idea. That problem is called overfitting, and it shows up when a model does well on its training data but poorly on new data. You can read more about that trap in our guide to overfitting, which explains why memorizing is not the same as learning.
Augmentation pushes back against memorization. When the same dog appears flipped, cropped, and slightly darker, memorizing one exact arrangement of pixels no longer works. The model has to find features that survive those changes, such as ears, fur texture, and overall shape. Those are the features that tend to work on new photos too.
What are the most common data augmentation techniques?
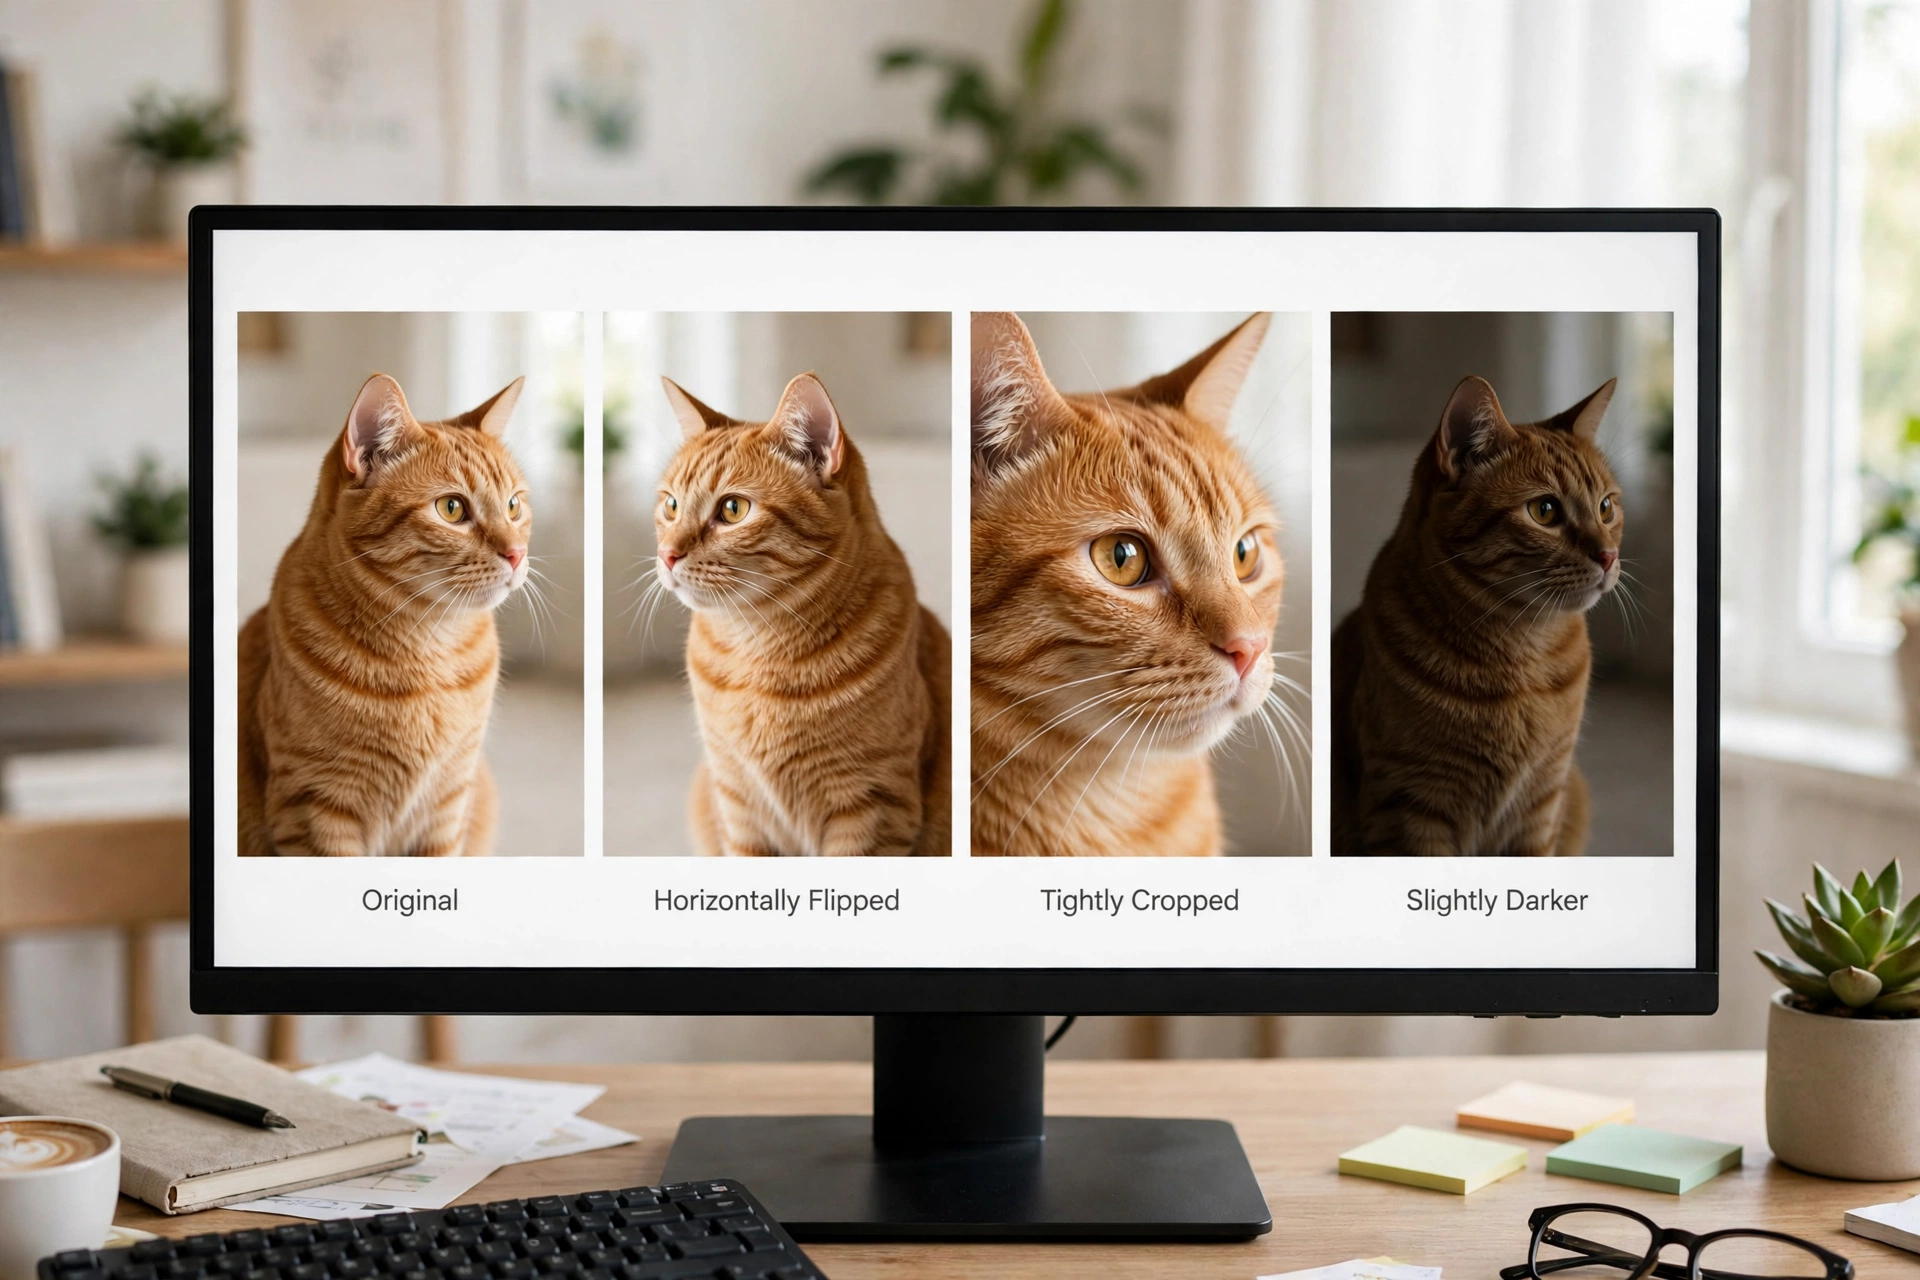
For images, the classics are easy to picture. Flipping a photo horizontally turns a left-facing cat into a right-facing one. Cropping zooms in on part of the scene, so the model learns to spot its subject even when it is not centered. Rotating by a few degrees mimics a slightly tilted camera, while adjusting brightness or contrast mimics different lighting.
Other techniques go further. Adding a small amount of noise imitates a grainy phone photo. Randomly hiding a small patch of the image, sometimes called cutout, forces the model to use the rest of the picture rather than leaning on one detail. Mixing two images together, a method known as mixup, creates a blended example that sits between two classes and encourages smoother, less overconfident decisions.
For further reading, see IBM’s data augmentation guide and TensorFlow’s data augmentation tutorial.
 When does data augmentation go wrong?
Augmentation only helps when the changed examples still look plausible. Flip a photo of a dog and you still have a dog. Flip a photo of text, though, and the letters become unreadable, which teaches the model nonsense. Rotate a photo of a handwritten “6” by 180 degrees and it starts to look like a “9,” which can confuse the label completely.
Too much change is another risk. If every training photo is heavily distorted, the model may learn to handle extreme cases that never appear in real use, while getting worse at ordinary ones. The usual fix is restraint: apply changes randomly, keep most of them mild, and always check the result on a separate test set that was not augmented. If accuracy on real, untouched examples falls, the augmentation is probably too aggressive.
How is data augmentation used in real projects?
In photo recognition, augmentation is almost routine. A team building a plant-identification app, for example, might start with a few hundred photos of each species, then flip, crop, and vary the brightness to cover different phones, seasons, and lighting. The app still needs real photos to start from, but augmentation helps it cope when a user photographs a leaf at an odd angle in uneven light.
Can you try data augmentation yourself?
You do not need a large project to get a feel for it. If you are learning image classification, try training a simple model twice: once on your original photos, and once with basic flipping and cropping added. Compare both on photos the models have never seen, and note which one holds up better.
For background, start with our complete guide to artificial intelligence, then our beginner guides to machine learning and deep learning, which explain the training loop that augmentation feeds into.
FAQs
Is data augmentation the same as collecting more data?
No. It creates variations of data you already have, rather than gathering new real examples. It is cheaper and faster, but it cannot add genuinely new information, such as a breed or a viewpoint that never appeared in the original set.
Does data augmentation work for text as well as images?
Yes, though the techniques differ. Text can be paraphrased, have words swapped for synonyms, or be back-translated through another language. The key rule is the same: the meaning and the label should stay intact after the change.
Can augmentation fix a biased dataset?
Not on its own. It multiplies the examples you have, including their biases. If a group or a category is underrepresented, you still need more real, diverse examples to fix that gap.
How much augmentation is too much?
There is no single number, because it depends on the data and the task. A good rule is to keep changes mild and realistic, apply them randomly, and judge the result on untouched test data. If test accuracy drops, dial the changes back.
Do you still need real data if you use augmentation?
Yes. Augmentation starts from real examples, so a tiny or poor-quality dataset will still limit what a model can learn. Think of it as stretching good data further, not as a substitute for it.
Conclusion
Data augmentation is a practical, widely used way to help AI models learn from limited data. By flipping, cropping, and gently varying the examples a model sees, it pushes the model toward real patterns instead of memorized details. A good next step is to try it on a small project of your own: pick a simple image task, add one or two mild techniques, and compare the result on photos the model has never seen. If you are also curious about the pitfalls, our guide to overfitting is a natural follow-up, because it explains exactly the problem augmentation is trying to reduce.