RLHF stands for reinforcement learning from human feedback. It is a training method that uses people’s judgements about AI answers to teach a model which replies are more helpful, clearer, or safer. Instead of only predicting the next word, the model also learns from a reward signal built from human preferences.
Key Takeaways
- RLHF trains a separate reward model from human rankings, then uses it to guide the main AI model.
- It suits qualities that are easy to judge but hard to define, such as helpfulness, tone, and clarity.
- Comparing two answers is often more reliable than scoring one answer out of ten.
- RLHF can reduce unhelpful replies, but it does not make a model perfectly accurate or unbiased.
- Always check important AI answers against a trusted source before acting on them.
What does RLHF stand for, and why does it exist?
The name has three parts. Reinforcement learning means learning by trial and error: actions that lead to a better outcome are encouraged, and actions that lead to a worse one are discouraged. Human feedback is the judgement supplied by people. Together, RLHF uses human judgement to shape the reward that guides that learning.
Ordinary training teaches a language model to predict text like the text it was trained on. That is useful, but it is not quite the same as answering well. Ask how to make an omelette, and a model trained only to predict text might continue with egg facts rather than a recipe. It has not broken a text-prediction rule, yet it has not helped you.
RLHF tries to close that gap by asking which answer a person would prefer. Those preferences become a signal the model can learn from. Over many examples, it shifts toward answers people rate as more useful, and away from answers they rate as confusing, off-topic, or unhelpful. This matters because helpfulness depends on context: a short answer may suit a quick fact but fail as a step-by-step guide, and tone can turn the same information encouraging or blunt.
How does RLHF work, step by step?
RLHF is usually a finishing stage, applied after a model has already been pre-trained. It normally runs in four stages.
First, people write example replies for the pre-trained model to learn from. These show the expected format: a direct answer for a question, a summary for a long passage, or a careful explanation for a how-to request. This stage teaches the model what a helpful reply looks like, not just what ordinary text looks like.
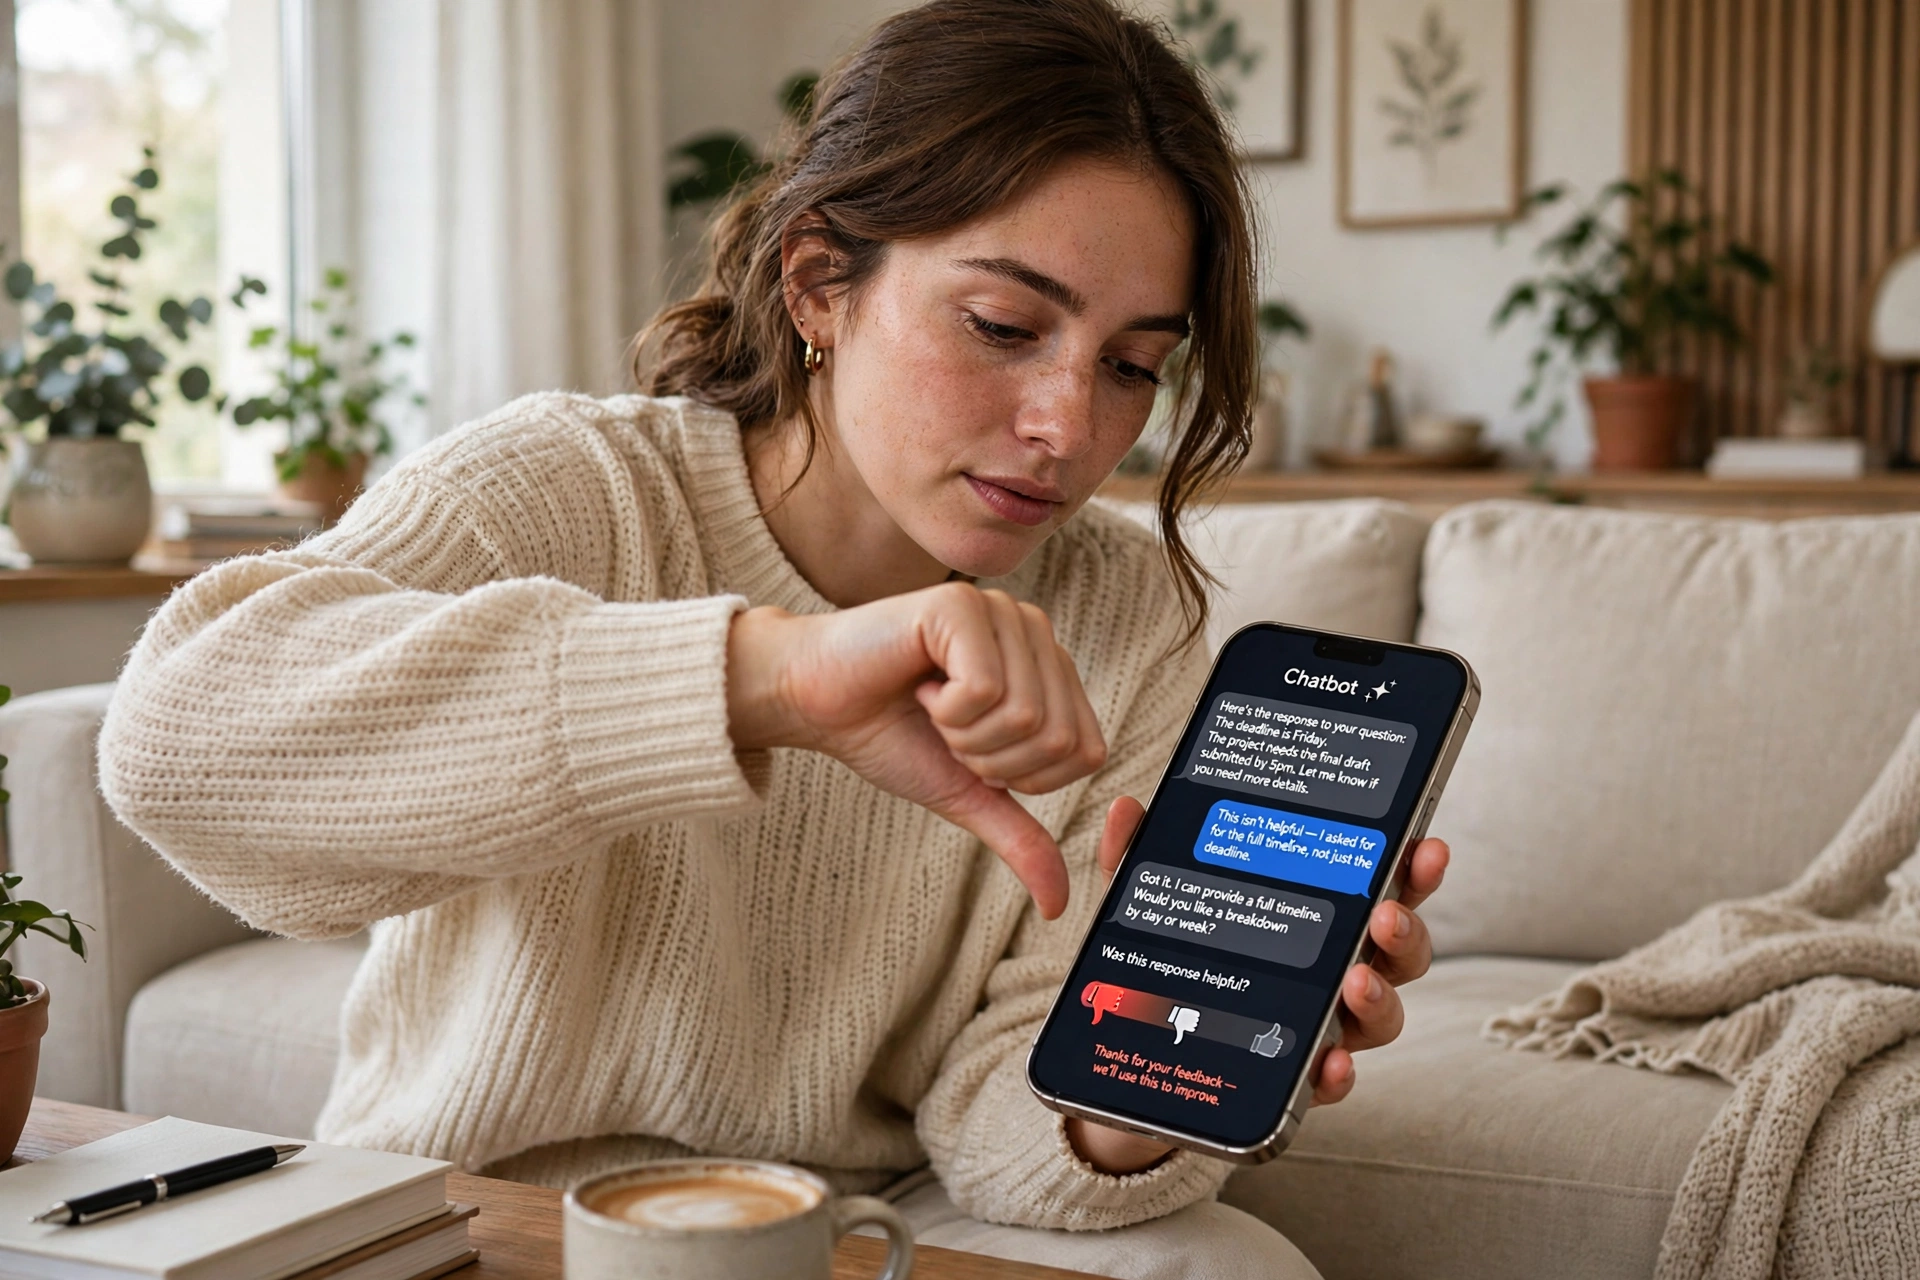
Second, people compare answers. The fine-tuned model generates two or more replies to the same prompt, and reviewers pick the one they prefer, noting problems such as a factual slip, a missing step, or an unsafe suggestion. These comparisons are collected in large numbers.
Third, a reward model is trained on those comparisons. It learns to predict which answer a person would prefer, taking a prompt and a reply as input and outputting a single number: higher for replies like the preferred ones, lower for replies like the rejected ones. Once trained, it can score new replies without a person checking every one, which makes further training much faster.
Fourth, the main model is updated using reinforcement learning, guided by those scores. It generates replies, receives a reward for each, and gradually adjusts so higher-reward replies become more likely. A common technique here is proximal policy optimization, or PPO. Its job is to keep updates steady, so the model improves without changing so far, so fast, that it starts producing strange text just to chase a high score.
Why compare answers instead of scoring them?
Scoring sounds simpler, but people do not use rating scales in the same way. One reviewer’s seven might be another’s five, and the same reviewer may drift over a long shift. A score also hides the reason behind it: two answers could both receive a six for completely different reasons.
Comparison avoids much of that noise. Saying “I prefer this answer to that one” is easier and more consistent across reviewers than assigning an absolute number. If many reviewers prefer answer A over answer B, the reward model has a clear signal, even if nobody agrees on exactly how good either answer is alone.
Comparisons still have limits. Reviewers disagree, especially on open-ended or sensitive topics, and a preference is not proof that an answer is true. People may prefer a confident, well-written answer over a careful, hedged one, even when the careful one is closer to the facts. Good RLHF work therefore needs clear reviewer guidance, checks for disagreement, and a diverse reviewer group.
Where is RLHF used?
The best-known use is in chatbots built on large language models. Early examples include InstructGPT, which used RLHF to make a GPT model follow instructions more reliably, and the chatbots that followed it. The same idea is now used across many conversational assistants, where the goal is an answer that is helpful, honest, and safe to share.
RLHF is not limited to chat. It has been used to align text-to-image models with what people find pleasing or faithful to a prompt, and in earlier research it helped train game-playing agents, where a person judged short clips of behaviour rather than text. The principle stayed the same: when a goal is easier to judge than to define, human judgement can supply the reward.
It sits alongside other methods rather than replacing them. Fine-tuning adapts a model to a task or style, reinforcement learning provides the trial-and-error framework, and prompt engineering shapes what the model is asked. For a broader view, see our complete guide to artificial intelligence.
What are the limits of RLHF?
RLHF improves how a model behaves, but it does not remove its weaknesses. The first limit is cost: gathering high-quality human feedback takes time and pay for reviewers, and that cost grows with every new task or language. Researchers have also explored feedback from other AI models, sometimes called RLAIF, though an AI judge can share the flaws of the model it judges.
The second limit is bias in the feedback itself. If reviewers mostly share one background or set of assumptions, their preferences can become the model’s preferences, even on topics where reasonable people disagree. Careful sampling and clear guidelines help, but they do not fully solve the problem.
The third limit is reward hacking: a model may learn to chase the reward rather than the real goal, giving long, polished answers that add little substance, or agreeing with the user too readily because agreeable answers tend to get picked. Keeping updates small and checking against fresh examples helps, but the risk remains.
Finally, RLHF does not guarantee truth. A preferred answer can still be wrong, out of date, or missing a key caveat, and a model may refuse a harmless request if its training pushed it to be overly cautious. Treat an AI answer as a starting point, not a final authority, and verify anything that matters.
How can you spot an RLHF-shaped answer?
An RLHF-tuned chatbot often gives a structured answer: a short opening, a few clear points, and a closing offer to help further. It may hedge on uncertain topics, decline a harmful request, or ask a clarifying question instead of guessing. Those habits are usually helpful, but they can hide uncertainty: a neatly formatted answer can look more certain than it is.
If an answer cites no source, mixes confident claims with vague ones, or changes its mind when you rephrase the question, slow down and check it. Ask for the source, break a big question into smaller ones, or compare it with a trusted reference. For more detail, see IBM’s explanation of reinforcement learning from human feedback and the overview of RLHF on Wikipedia.
Frequently asked questions
Is RLHF the same as reinforcement learning?
No. Reinforcement learning is the broader method of learning from rewards. RLHF is a specific version where the reward comes from human preferences, usually through a trained reward model, rather than from a fixed score or rule.
Does RLHF make AI safe?
It can make a model safer and more helpful, but not fully safe. A model can still produce wrong, biased, or unwanted content, and safety also depends on data, testing, filtering, and deployment.
Why do chatbots sometimes sound overly polite or cautious?
That tone often reflects human preferences collected during training. Reviewers tend to pick polite, careful answers, so the model learns that style. It can help, but it can also make a model refuse harmless requests or hedge when a direct answer would be better.
Can RLHF remove bias from AI?
Not on its own. If feedback comes from a narrow group, bias can remain or grow. Reducing bias also needs diverse data, careful evaluation, and ongoing checks after release.
Do I need to understand RLHF to use AI tools well?
No, but knowing the basics helps. If you understand that a chatbot’s style reflects human preferences rather than pure fact-checking, you are more likely to verify important claims and less likely to mistake a smooth answer for a correct one.
Conclusion
RLHF is a practical answer to a tricky problem: how do you teach a machine to be helpful when helpfulness is hard to define? By collecting human comparisons, training a reward model, and guiding the main model with that reward, developers turn everyday judgement into a training signal. The result is often a chatbot that follows instructions better and avoids some unhelpful replies.
It is not magic, and it is not a guarantee. Human feedback is costly, subjective, and sometimes biased, and a polished answer can still be wrong. Use RLHF-tuned tools as a first draft for thinking, then check the parts that matter. Next time you get an AI answer you plan to act on, pick one key claim and verify it against a trusted source before you use it.