Zero-shot learning lets an AI model handle a new category or task even though it was never trained on labelled examples of that exact thing. Instead, it uses descriptions, attributes, and knowledge picked up elsewhere to make a sensible guess — reasoning from what it already understands, rather than repeating what it has memorised.
Key Takeaways
- Zero-shot learning uses no labelled examples of the new category itself.
- Descriptions, attributes, or related knowledge bridge the gap.
- It helps when labelling data would be slow, costly, or impractical.
- It is not always right, especially on unusual or ambiguous cases.
- Clear labels, good descriptions, and a human check make results far more trustworthy.
What does zero-shot learning actually mean?
Most machine learning works through examples: show a model thousands of pictures labelled “cat” and “dog,” and it learns to tell them apart. That breaks down when a new category appears with no labelled pictures. Collecting thousands more examples is often slow, expensive, or impractical — especially if the category is rare.
Zero-shot learning takes a different route. The model gets no examples of the unseen category, but it does get a description: a written account, a list of attributes, or a shared space where words and images sit close together when they mean similar things. It then compares the new input with those descriptions and picks the best match.
Imagine you have never seen a zebra, but someone tells you it looks like a horse with black-and-white stripes. When you finally meet one, you are not lost: you combine two familiar ideas into a new recognition. Note the precision, though — “zero” refers to examples of that specific new class, not to all learning.
How does zero-shot learning work?
At its heart, this is a matching problem. The model must connect a new input — a photo or a piece of text — with a category it has not been trained on directly. Descriptions act as the bridge. If the model already understands language and images in a shared way, it can measure how closely a new photo resembles the description of each candidate category.
In image tasks, a model trained on images with captions learns which visual features go with which words. Later, give it a new category name or short description, and it checks which description fits best, without a labelled example. In text tasks, the idea is similar: a zero-shot classifier can sort messages into topics such as “delivery” or “refund” by comparing each message with those labels, without hundreds of labelled messages per topic.
How is it different from few-shot learning?
Zero-shot and few-shot learning are close cousins. In few-shot learning, the model gets a small handful of examples of the new category — perhaps five or ten — and uses those to adjust. In zero-shot learning, it gets none. Few-shot learning usually gives better accuracy because the examples ground the model, but zero-shot is faster to try and needs no new labelling.
Picture a small shop sorting photos of a new product line. Few-shot learning asks you to label a few photos first; zero-shot learning lets you start straight away with names and short descriptions, with a few mistakes but results in minutes. Many projects start zero-shot and add examples only where the model keeps going wrong. Both sit inside machine learning and still need testing on real examples.
Where is zero-shot learning used today?
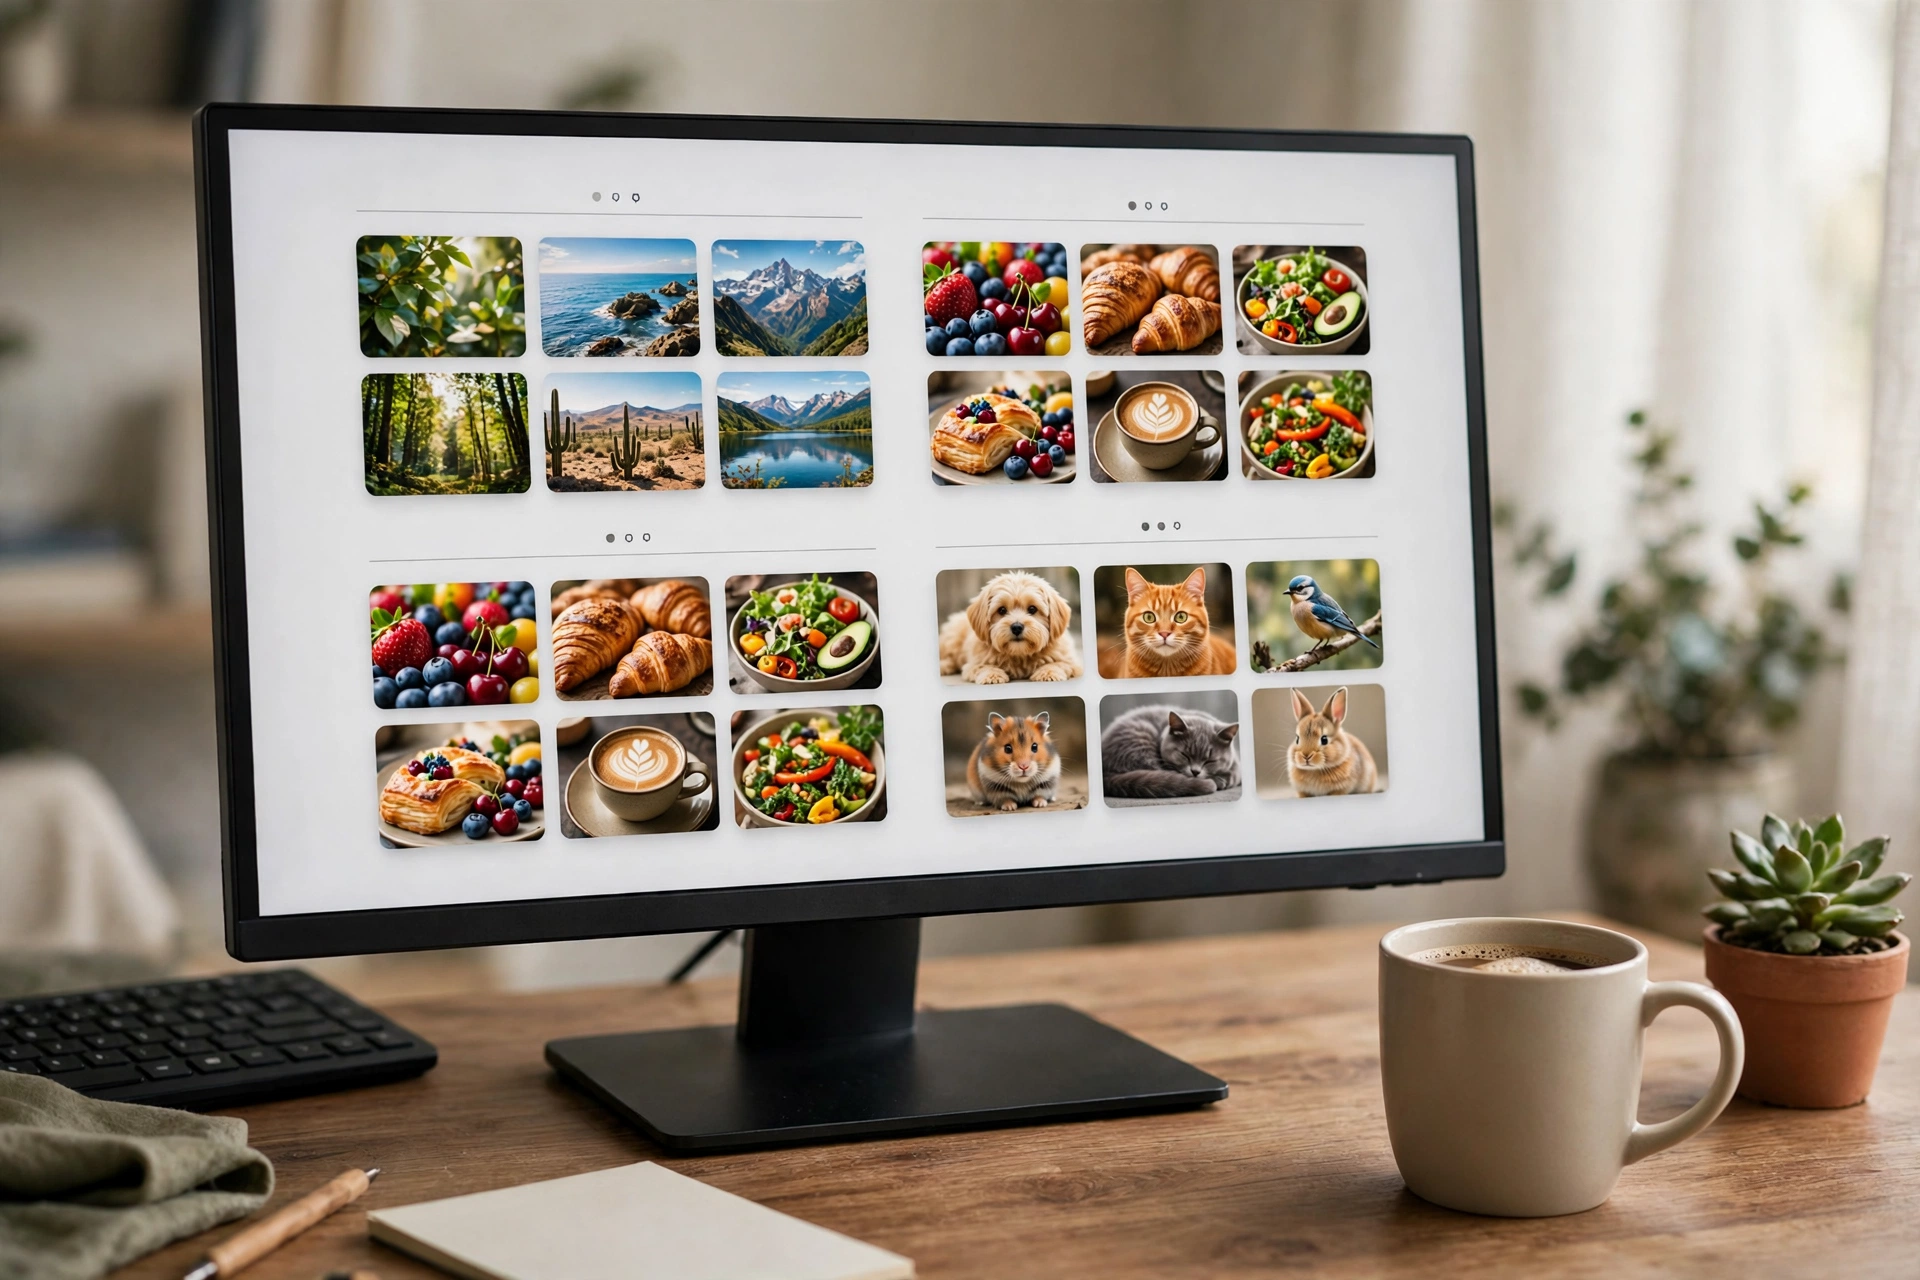
Sorting and tagging content is a common use. News sites, shops, and support teams often group text or images into categories that change over time; with zero-shot classification, they can add a category by writing a clear label and description, rather than rebuilding a dataset. It also helps search, where a plain-language query must match items never labelled with that exact wording.
Image recognition is another natural fit: a model trained on images and descriptions can often recognise a new object from its description alone. Chatbots use a similar idea when they interpret a request in a form they have not seen before. Researchers also use zero-shot tests to judge generalisation — handling new categories sensibly suggests transferable understanding, not just memorisation.
What are its limits and risks?
Zero-shot learning is not a cure-all, and its failures can be quiet: a model may sound confident while being wrong, with no direct examples to anchor it. Ambiguous labels are a frequent culprit — if two categories overlap, or a label means different things in different contexts, the model must guess which meaning you intended.
Bias is another real concern. Earlier training shapes what a model treats as typical, so an unseen category that does not fit its learned patterns may be misclassified more often. That matters most in sensitive areas such as hiring, lending, or health, where a wrong label can affect a real person — so zero-shot tools should not be the sole decision-maker there. Test on a small, realistic sample first to reveal weak labels and edge cases.
How can you try it sensibly?
Start small and clear: pick a handful of categories, write plain descriptions, and test on examples you understand. Look at the mistakes first — often one confusing label explains a whole cluster of errors, and fixing the description beats collecting new data.
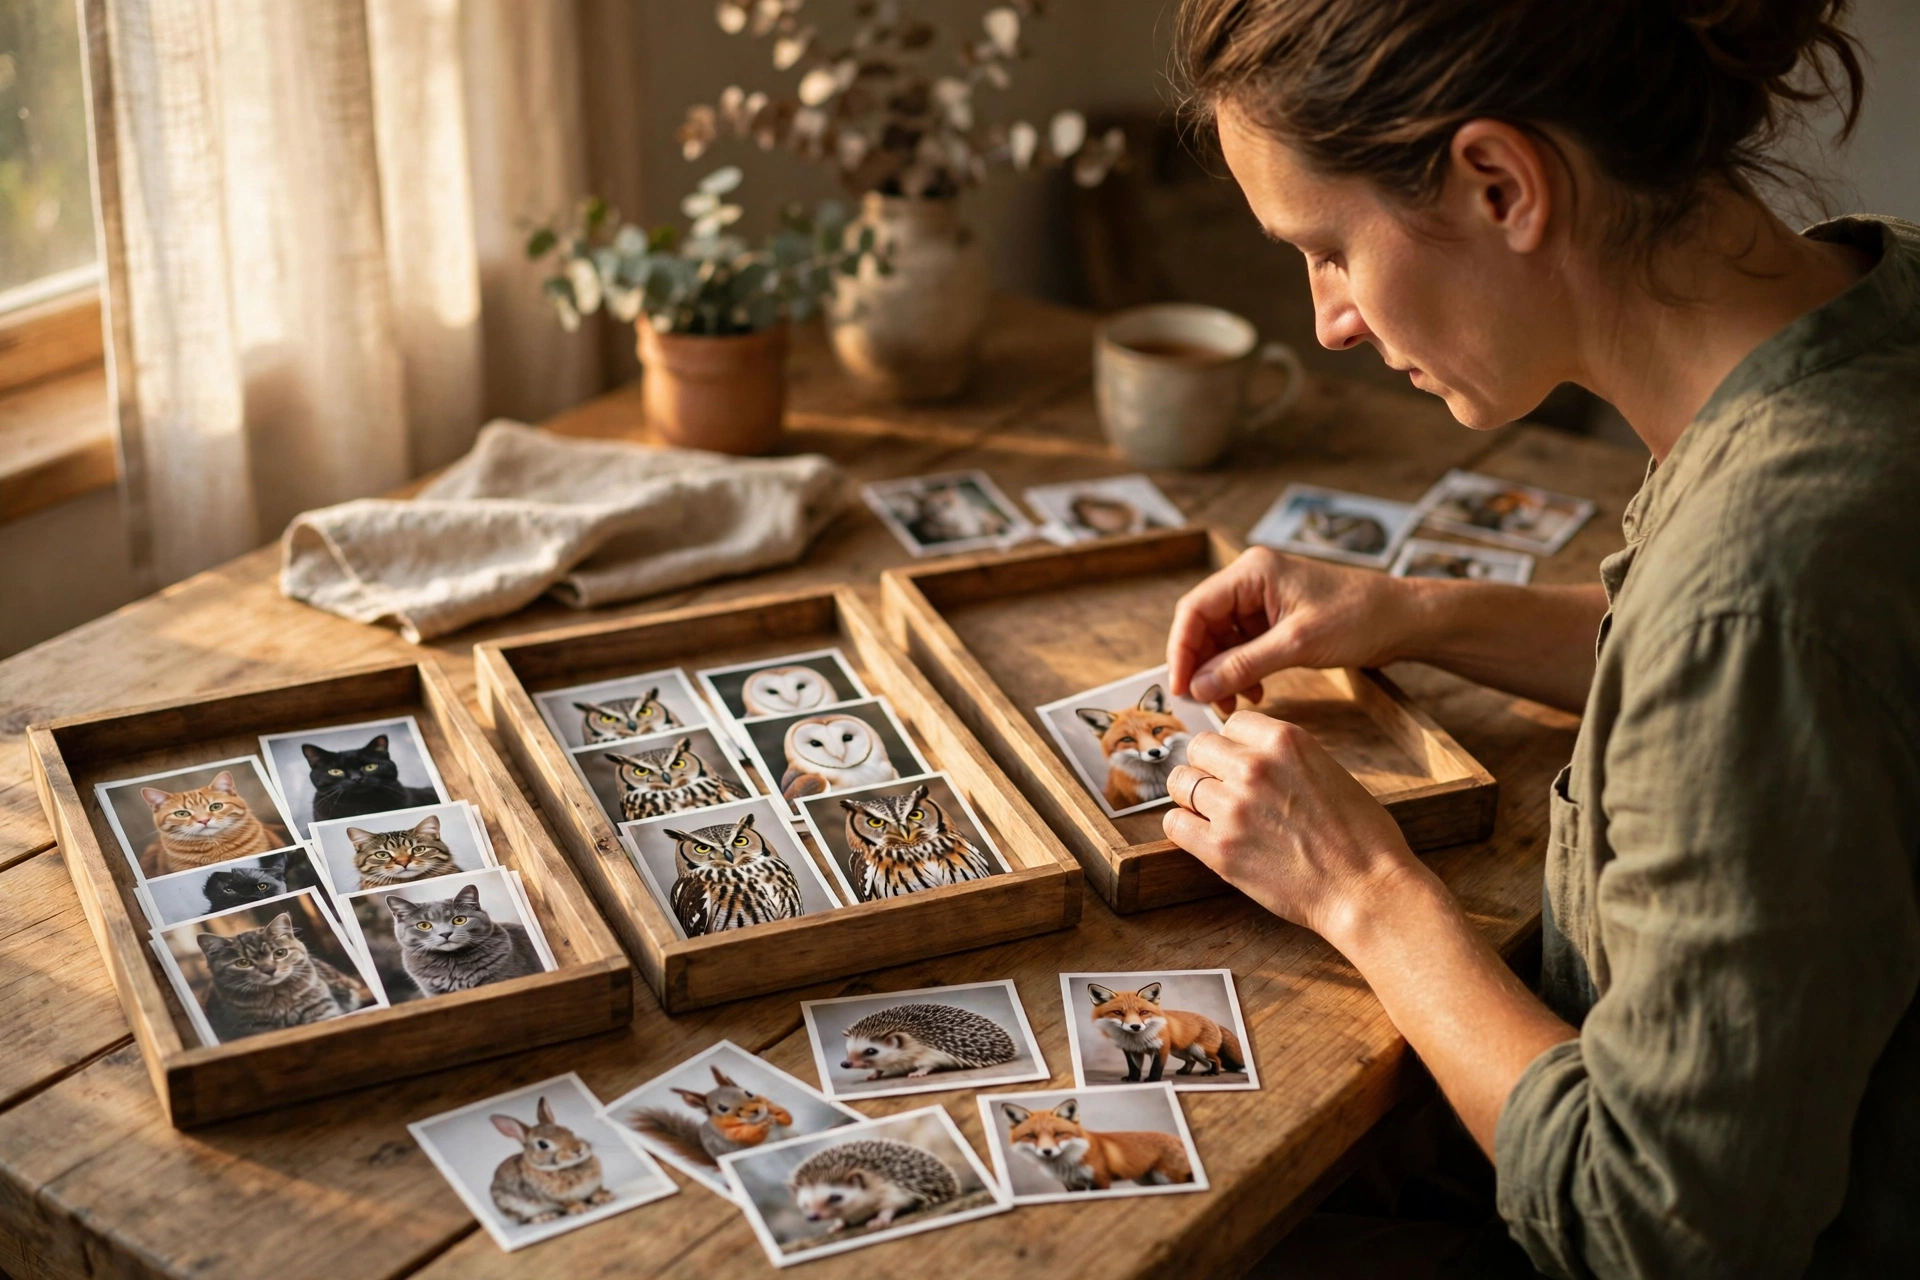
Then compare with a simple baseline, such as a keyword rule or a manual sort of a small sample. If zero-shot is clearly worse, the task may need examples or better labels; if it is close, you have saved a lot of labelling effort. Finally, keep a human in the loop where it counts, using zero-shot output as a first draft to check. Clear prompt wording and honest testing turn a demo into something reliable. For broader grounding, see the complete guide to artificial intelligence.
Frequently Asked Questions
Is zero-shot learning the same as learning without any training?
No. The model is usually trained on a large amount of related data first. “Zero-shot” means it gets no labelled examples of the new category itself, not that it starts from nothing.
Can zero-shot learning recognise anything at all?
No, it still needs a useful description or related knowledge. A category with no description, or one very different from anything the model has seen, is likely to be guessed poorly.
Is zero-shot learning better than few-shot learning?
Not usually on accuracy. Few-shot adds a few examples, which often helps a lot. Zero-shot wins on speed and convenience, because it needs no new labelling before you start.
Where should I avoid using zero-shot learning alone?
Avoid relying on it alone for high-stakes decisions, such as medical, financial, or hiring judgments. Use it as a helper, with human review, and check its errors on realistic examples first.
How do I improve a zero-shot result?
Rewrite unclear labels, add distinctive attributes to your descriptions, test on real examples, and consider adding a few examples — moving to few-shot — for categories that keep failing.
Conclusion
Zero-shot learning is a shortcut with a purpose: it lets AI tackle new categories from descriptions when examples are scarce or impractical to collect. It works because modern models can connect words, attributes, and images in a shared understanding, not because they know the unseen category in advance. Used carefully — with clear labels, realistic testing, and human checks where it matters — it can save a great deal of time. The practical next step: pick one small sorting or tagging task, write clear descriptions for each category, and test a zero-shot approach on a sample you can check by hand. For deeper background, IBM’s guide to zero-shot learning and Hugging Face’s zero-shot text classification guide are good places to continue.