Active learning is a way for an AI model to ask for help with the examples it finds most confusing, instead of waiting for a person to label everything. It starts with a small labelled set, scans a larger unlabelled pile, picks the examples likely to teach it most, and sends those to a human. The new labels go back into training, and the cycle repeats.
Think of it as studying smarter, not longer. A student who only rereads pages they already know will not improve as fast as one who focuses on the questions they keep getting wrong. Active learning aims to do the same for a model: spend the labelling budget where it should make the biggest difference.
Key Takeaways
- Active learning lets a model choose which unlabelled examples should be labelled next.
- It is most useful when labelling is slow, expensive, or needs expert knowledge.
- Common strategies include uncertainty sampling, committee disagreement, and diversity sampling.
- It does not remove the need for good labels, careful checks, or a representative test set.
- Used well, it can cut labelling effort, but it is not a shortcut around data quality.
Why does labelling matter so much?
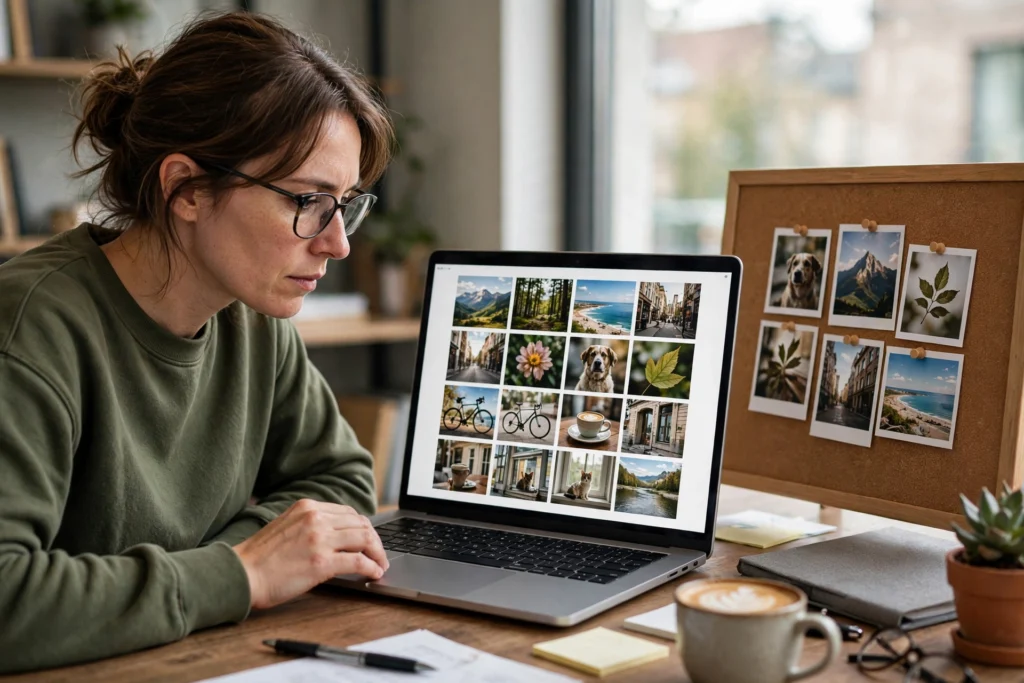
Most supervised machine learning depends on labelled examples. A model that sorts photos into cats and dogs needs plenty of photos already marked as cat or dog before it can guess well on new ones. Collecting those labels can take hours, need specialists, or involve sensitive material that must be handled carefully.
Unlabelled data, by contrast, is often cheap: cameras, sensors, and websites produce it in huge amounts. If a team labels examples at random, it may spend a lot of time on easy cases the model already understands, while missing the borderline cases that would actually change its decisions. Active learning flips the order, so a person labels a smaller, better-chosen batch first.
How does the active learning loop work?
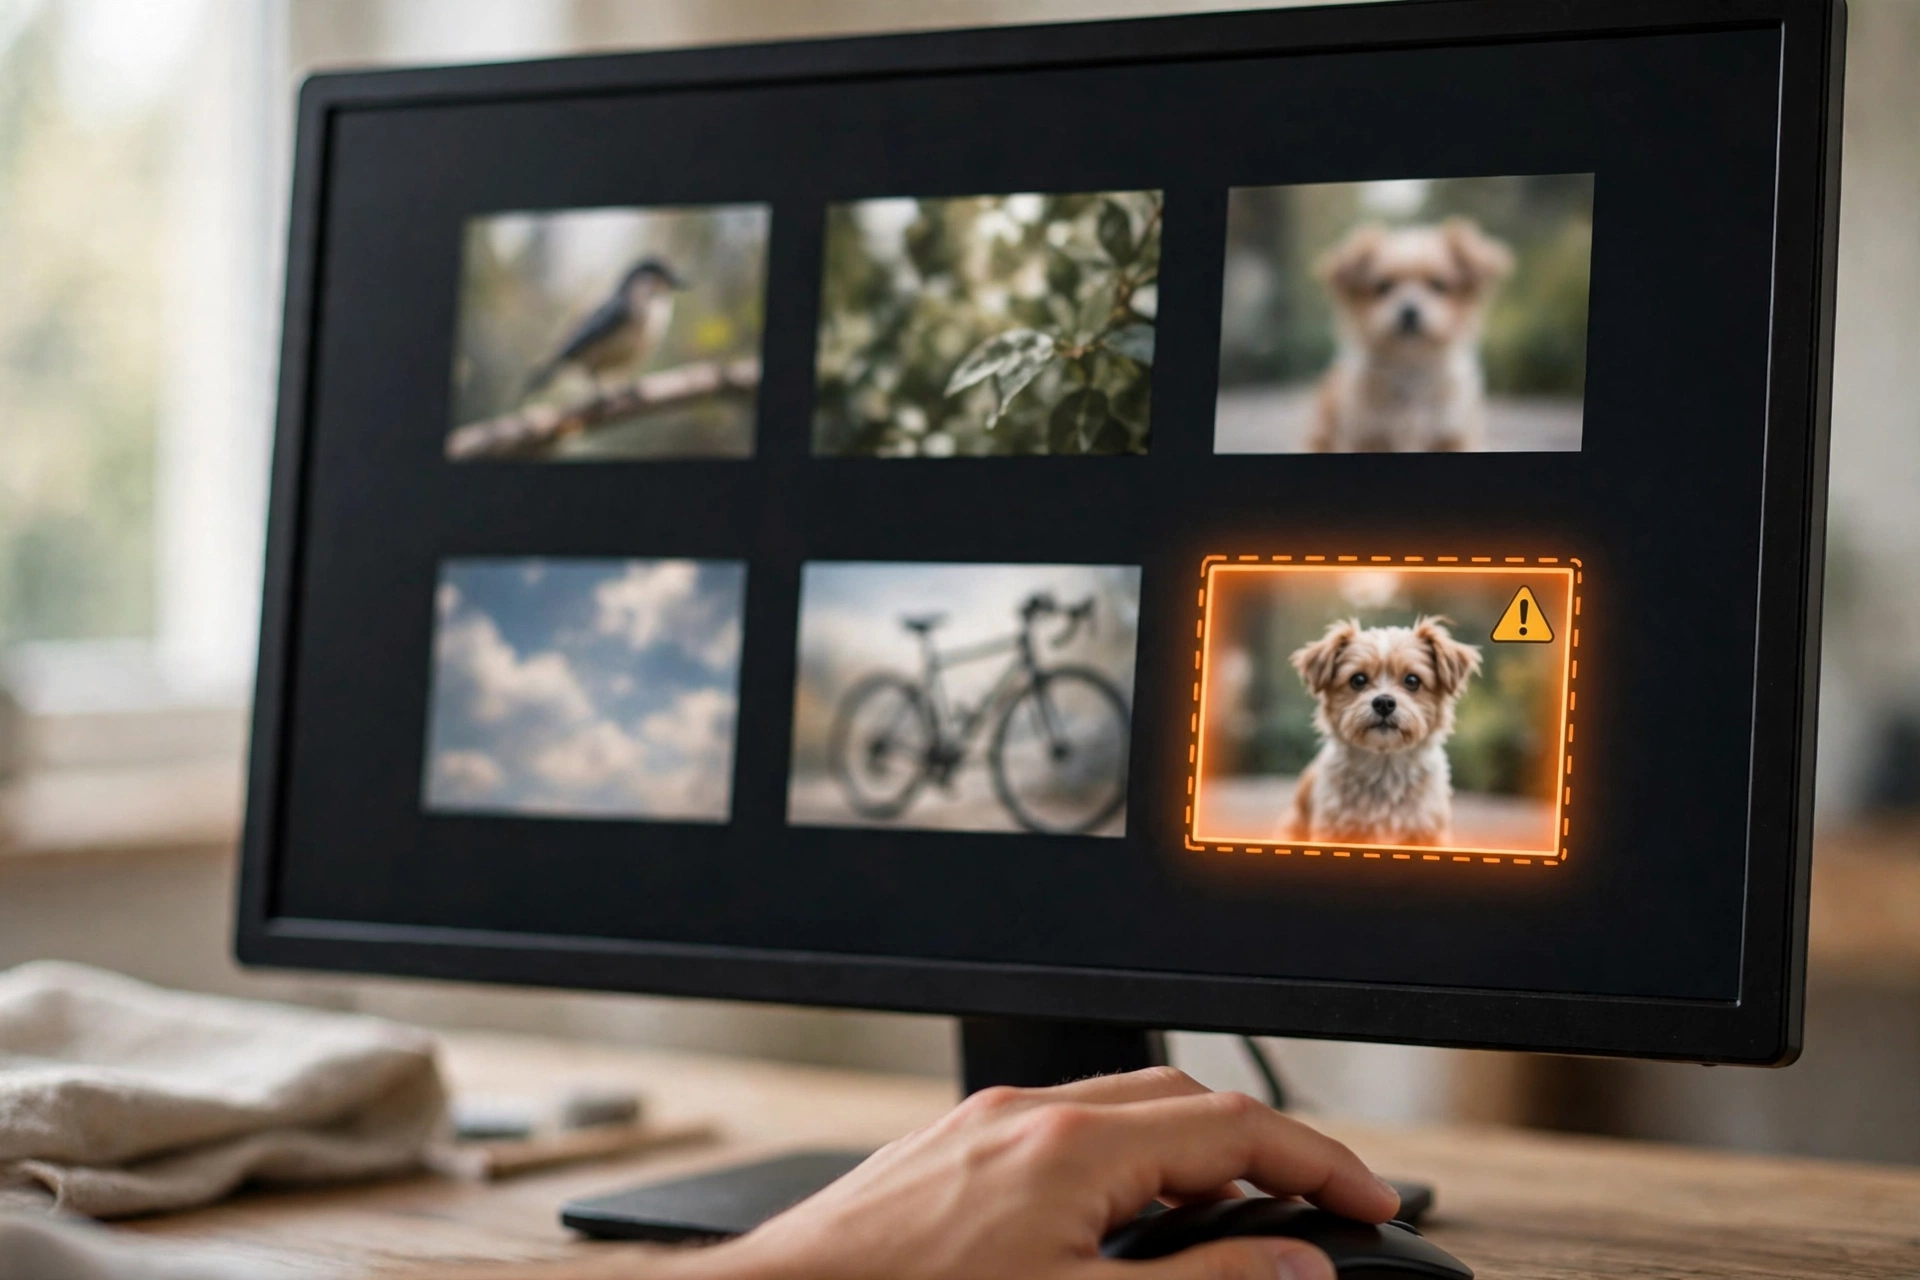
First, a team trains an initial model on a small labelled set. It does not need to be perfect; it just needs to be good enough to spot which examples look uncertain or unusual. Next, the model scores the unlabelled examples and the top-ranked ones go to a human annotator, sometimes called an oracle in research papers. That is simply a person with the knowledge to give the right label.
Then the new labels are added to the training set and the model is retrained. The loop repeats until the budget runs out, the model stops improving much on a held-out test set, or the remaining examples look mostly familiar. Stopping early matters: labelling forever is not the goal, and a model can still be checked and improved in other ways.
What are the main query strategies?
A query strategy is the rule for choosing what to ask about next. Uncertainty sampling is the most common starting point: the model picks examples where its prediction is least confident. If it is torn between two classes, or gives low confidence to every class, that example is a good candidate. Margin sampling is a close cousin, looking at the gap between the top two predicted classes: a tiny gap means real doubt.
Query by committee takes a different angle. Several models are trained on the same labelled data, then they vote on unlabelled examples. When the committee disagrees strongly, a human label can settle the argument. This works well when you can afford more than one model, and it can catch uncertainty that a single model hides.
Diversity sampling guards against repetition. Picking only the most uncertain examples can produce a batch of near-identical cases, which teaches the model the same lesson many times. Diversity methods spread the picks across different parts of the data, so the batch covers more ground. Many practical systems combine the two: shortlist uncertain examples, then choose a varied set from that shortlist.
Expected model change and expected error reduction go further and try to estimate how much a label would change the model or reduce its errors. They can be powerful, but they are often more expensive to compute, so teams tend to use them when labelling is very costly and the extra computation is worth it.
When is active learning a good fit?
Active learning shines when labels are the bottleneck. Medical image review, legal document sorting, and specialist inspection are classic examples, because each label needs training and care. It also helps when a dataset is large but mostly routine, with only a small share of tricky cases worth a human look.
It fits less well when labelling is already cheap, or when the model is so weak at the start that its rankings are mostly noise. In that case, a larger random labelled set may be a better first step. It also needs a sensible test set. If you only test on examples the model chose, you may get a flattering picture; a separate, representative test set keeps the evaluation honest.
Batch size is another practical point. Labelling one example at a time gives the freshest model each round, but it can be slow for a human team. Labelling in batches is more efficient, yet a large batch chosen from one model version may contain duplicates. A modest batch, with a diversity check, is often a workable middle ground.
What can go wrong?
Active learning can introduce its own biases. Because the model chooses the training data, the labelled set may end up skewed toward hard or unusual examples. That can help learning, but it means the training distribution no longer matches everyday data. Keeping a separate test set, and checking performance on ordinary cases, helps catch this.
Label quality matters even more here. A wrong label on a highly influential example can mislead the model more than a wrong label on a routine one. Clear guidelines, a second review for disputed cases, and a way to flag ambiguous examples all help. If annotators disagree often, that disagreement itself is useful: the example may be unclear, the guidelines may need work, or the classes may overlap.
There is also a human cost. Asking people to label only the hardest, most ambiguous cases all day can be tiring and error-prone. Mixing in some straightforward checks, rotating annotators, and setting realistic daily targets can keep quality up. The goal is to respect the annotator’s time, not just the model’s appetite for data.
How does it relate to other learning styles?
In ordinary supervised learning, the labelled set is fixed in advance and the model trains on all of it. In semi-supervised learning, the model also learns from unlabelled data, but usually without asking a human for new labels. Active learning adds that asking step: the model requests labels for specific examples.
It also pairs naturally with data labelling workflows. A team might start with active learning to build a strong initial set, then use semi-supervised methods to make the most of the remaining unlabelled data. None of these methods removes the need for human judgement. They change where that judgement is spent, so experts focus on decisions that teach the model most, rather than on thousands of obvious cases.
How can a small team try it in practice?
Start small and measurable. Pick one clear task, such as sorting support messages or tagging product photos, and set aside a test set before you begin. Label a modest initial set, train a simple model, and run one active learning round with uncertainty sampling. Compare the result with a model trained on the same number of randomly chosen labels. That comparison, even on a small scale, tells you more than a grand plan will.
Keep notes on what the model asks for. If it keeps picking the same kind of example, check whether those examples are genuinely informative or just noisy, mislabelled, or outside the task’s scope. If annotators keep disagreeing, pause and clarify the guidelines before labelling more. A short pilot, reviewed honestly, beats a large labelling run built on shaky definitions.
Frequently Asked Questions
Is active learning the same as supervised learning?
No, though they are closely related. Supervised learning trains on a fixed labelled set. Active learning is a supervised approach with an extra loop: the model repeatedly asks for labels on the unlabelled examples it thinks will help most, so the labelled set grows in a targeted way.
Does active learning mean I need fewer labels overall?
Often, yes, but not always. In many tasks it reaches a given accuracy with fewer labels than random sampling. The saving depends on the data, the model, and label quality. It is best treated as a way to spend a labelling budget wisely, not as a promise to cut it by a fixed amount.
Who provides the labels in active learning?
A human expert, a trained annotator, or sometimes another system with reliable answers. In research this source is often called an oracle. In practice, it is usually a person, so clear guidelines and quality checks still matter a great deal.
Can active learning work with images, text, and tables?
Yes. The idea applies to any task where labels are costly and unlabelled examples are plentiful. Image classification, text sorting, and tabular prediction can all use it, though the best query strategy and the way uncertainty is measured will differ by task.
What is the biggest mistake beginners make?
Trusting the model’s choices without a separate test set. If you only measure progress on examples the model selected, results can look better than they are. Always keep a representative test set aside, check ordinary cases as well as hard ones, and review label disagreements instead of ignoring them.
Conclusion
Active learning is a practical answer to a common problem: plenty of data, but not enough labels. By letting the model point to the examples it finds most uncertain, most disputed, or most different from what it has seen, teams can focus human effort where it teaches the most. It works best with clear labels, a representative test set, and a willingness to stop and check, rather than labelling on autopilot.
A good next step is a small pilot on one task you already understand. Label a modest starter set, run a few uncertainty-sampling rounds, and compare against random labelling on a held-out test set. If the targeted labels help, you have a solid case for using active learning more widely; if they do not, you have learned something useful about your data before spending a larger budget.