AI inference is the moment a trained AI model stops learning and starts working. You give it new input — a question, a photo, a voice clip — and it uses patterns learned during training to produce an answer, a prediction, or a decision.
That distinction matters because most of what we call “using AI” is inference, not training. Training happens once, or now and then, on powerful computers. Inference happens every time you press send. If training is like studying for an exam, inference is sitting the exam: you work from what you already know, not from a textbook you can open mid-test.
Key Takeaways
- AI inference means running a trained model on new input to get an output.
- Training teaches the model; inference applies what it learned.
- The same model can run in the cloud, on a server, or on your phone — where it runs changes speed, cost, and privacy.
- Good inference balances speed, accuracy, and cost at scale.
- A confident-sounding answer is not proof it is correct, so check important results.
How is inference different from training?
Training and inference ask the same model to do opposite jobs. During training, the model sees many examples, makes guesses, gets corrected, and slowly adjusts its internal settings — called weights — so its guesses improve. That needs huge amounts of data and computing power, and it can take days or weeks.
Inference is lighter. The weights are already fixed. The model takes your input, runs it through those weights in a single forward pass, and returns a result. It does not learn from your question in that moment. Tomorrow, the same question should give a very similar answer, unless the model, its settings, or the system around it has changed.
Take a spam filter. Training teaches it what spam tends to look like: certain words, odd links, mismatched sender names. Inference is what happens when a new email arrives and the filter scores it in a fraction of a second. It is not retraining on that one email; it is applying a lesson already learned.
That is also why a model can be strong on familiar examples and shaky on new ones. If your input differs a lot from its training data, inference may be less reliable. This gap is a common reason AI answers feel off.
For the broader picture, see our complete guide: What Is Artificial Intelligence? The Complete Guide
What actually happens during inference?
In plain terms, inference has four quick steps.
First, your input is prepared. Text is broken into pieces the model can work with, an image is resized and cleaned up, or audio is turned into a readable form. Messy input usually leads to messy output, so this step matters more than it looks.
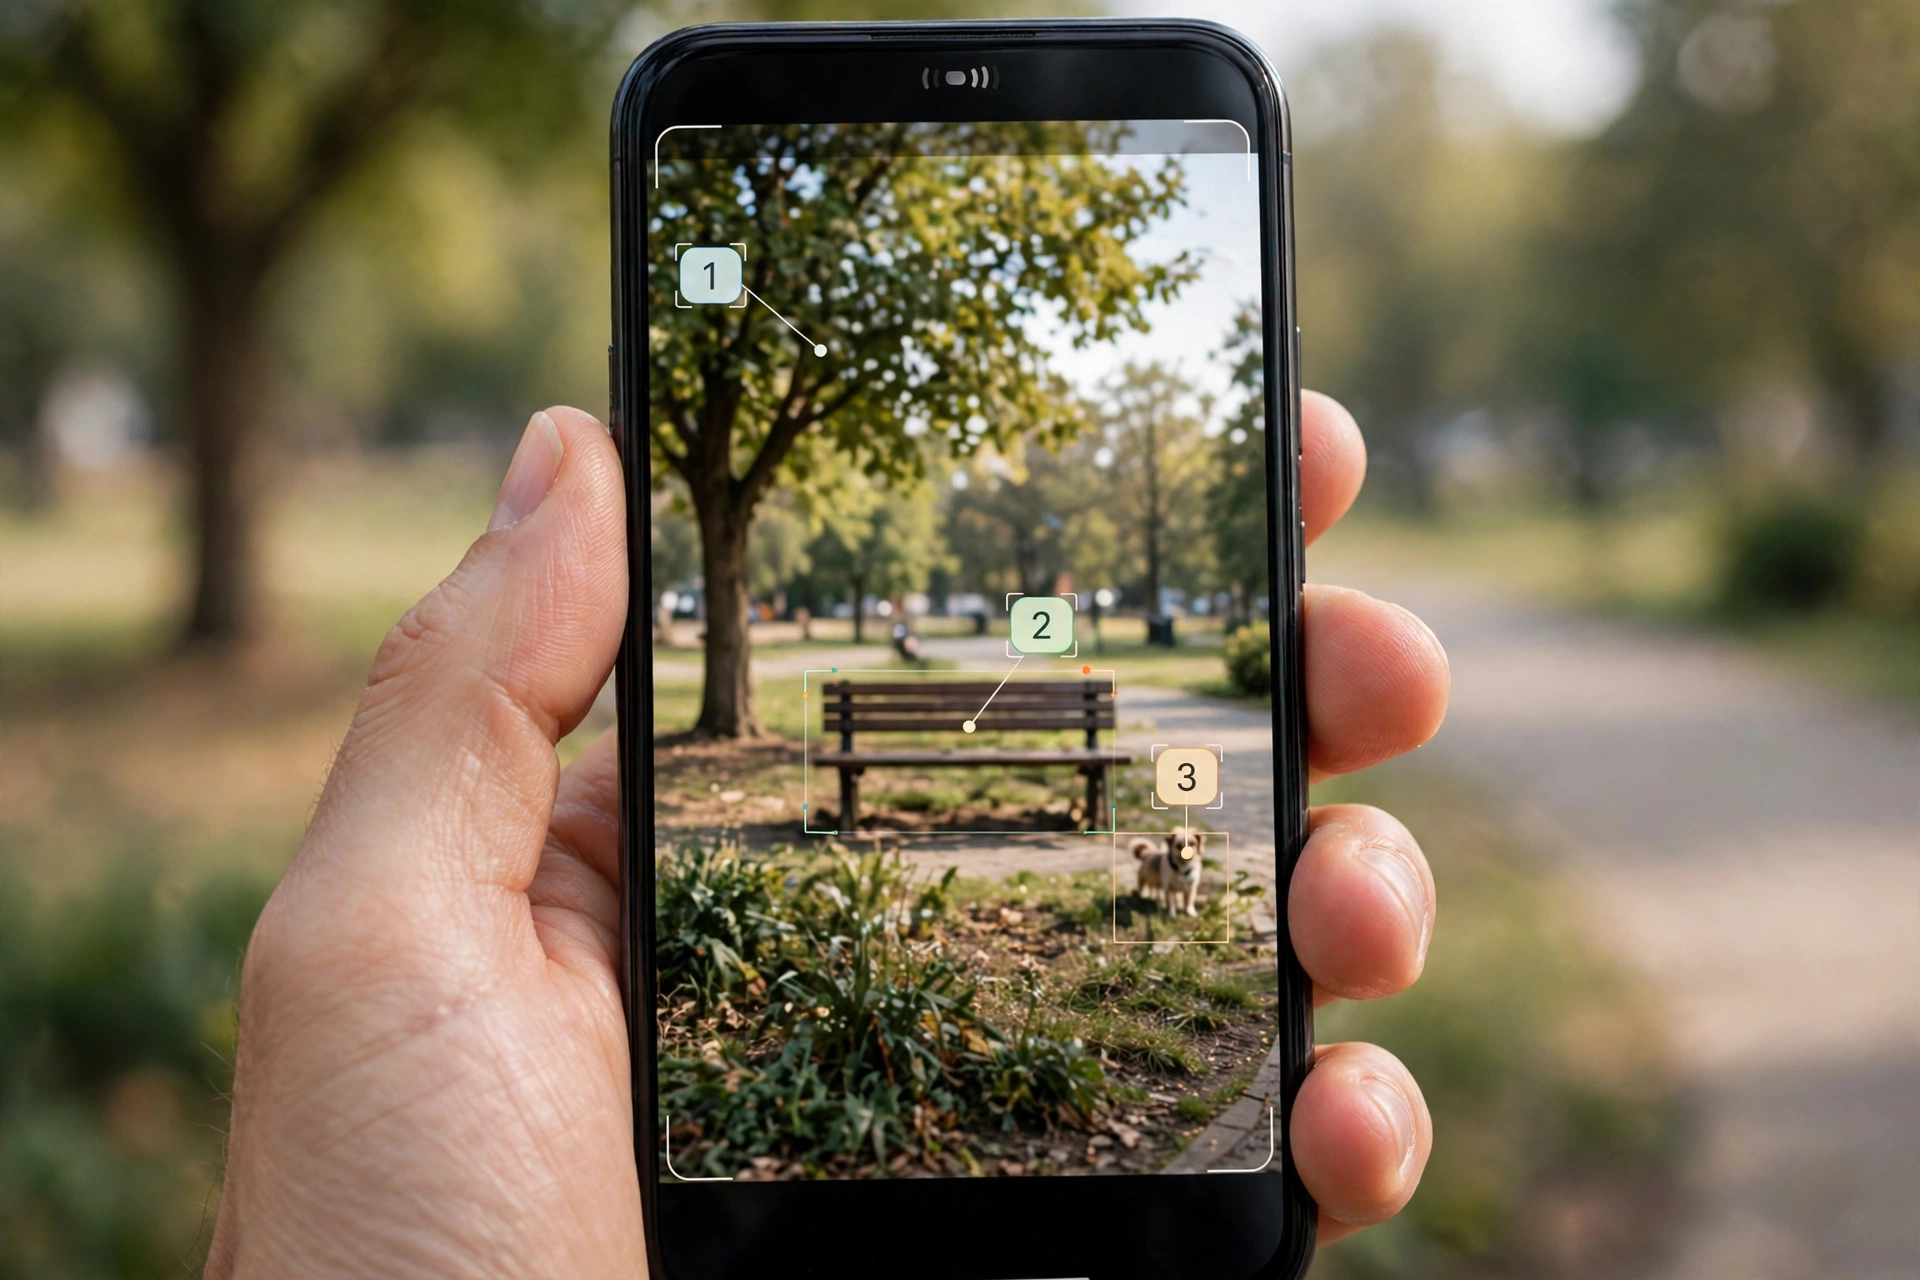
Second, the model processes that input. A language model predicts what comes next, piece by piece. An image model recognises shapes and context and labels what it sees. A recommendation system scores options and ranks them.
Third, the raw output is shaped into something useful. A chatbot turns predicted text into a readable reply. A photo app turns scores into a caption. A voice assistant turns text into speech. This step can include formatting and simple checks, such as making sure a date looks right.
Fourth, the result is returned to you. The system may also log how long it took, which helps teams spot slow requests — but that logging does not mean the model learned from your question.
The model is not understanding in the human sense. It is matching patterns. Keeping that in mind helps you judge its answers more fairly, and check the important ones.
Where does inference run: cloud, server, or device?
Where inference runs is a practical choice, and each option trades speed, cost, and privacy differently.
Cloud inference is most common for large models. Your request travels to a data centre, runs on powerful hardware, and comes back as an answer. It can handle huge models and sudden spikes, which is why chatbots usually work this way. The downside is the round trip: it needs a good connection, and your input leaves your device.
On-device inference, often called edge inference, runs the model where you are — on a phone, laptop, camera, or smart speaker. It can feel instant, with no network delay, and it can keep sensitive input local. That is why features like face unlock and live captions work with patchy signal. The trade-off is size: the model must be small and efficient enough to fit on the device. Our guide to Edge AI explains this side in detail, and Model Distillation shows how a big model can teach a smaller one a similar job.
Between those extremes, a business may run its own servers, controlling data and costs more closely while still serving many users. Many real products mix all three: a quick check on your device, a heavier job in the cloud, and a fallback if one route fails.
For most users, the location is invisible until something goes wrong: a slow reply, a feature that needs Wi-Fi, or a question about where your photo went. Asking “where does this run?” is a good habit when you start relying on an AI feature.
Why do some AI answers take longer than others?
Length is the biggest factor for text. A short answer needs fewer steps than a long essay, because the model generates text piece by piece. A detailed reply or a long conversation adds steps, and each step adds time.
Model size matters too. A larger model can handle more nuance, but it needs more computing power for every request. A smaller, well-tuned model may answer a simple question just as well and much faster. That is why apps often use a small model for quick tasks and a larger one only when the task is complex.
Load matters as well. If thousands of people ask at once, requests queue up. Hardware, network speed, and how the system batches requests together all play a part.
Then there is the work around the model: fetching context, checking a document, running a safety filter, or calling another tool. Those steps are not the model “thinking” slowly — they are the app doing extra jobs before it shows a finished answer.
You cannot control most of this, but you can control your prompt. A clear, specific question often gets a useful answer faster than a vague one that forces the model to guess what you meant. Our guide to Machine Learning covers how models learn those patterns in the first place.
What can go wrong during inference?
Inference can fail quietly, which makes it worth understanding. The model rarely announces that it is unsure — it just gives its best guess.
The most common problem is input it has not seen much of before: a photo in unusual light, a question in slang, or a document format it rarely handles. The answer may still sound confident, which is why confident wording is not proof of correctness.
Settings around generation can also mislead. For text models, settings that control randomness affect whether answers are predictable or creative. A very creative setting can produce lively but less reliable answers; a very strict one can produce safe but dull ones. Neither makes the model “smarter” — they just change how it picks among likely options.
System design matters too. If an app shows only the top answer, without sources or alternatives, you have less to check. If it presents an AI guess as a fact — a date, a price, a health claim — the risk is higher than if it presents it as a suggestion to verify.
The practical fix is simple: treat inference output as a draft, not a verdict. For anything affecting money, health, safety, or a decision you cannot easily undo, check the source or ask someone who knows.
How do teams make inference faster and cheaper?
Running a model millions of times a day is expensive, so teams work hard to make inference efficient without wrecking quality.
One approach is to use a smaller model for the job at hand. Another is to compress a model, trading a little precision for a lot of speed. A third is to cache common answers, so repeated questions do not need a full run every time. A fourth is to batch similar requests together, so hardware is used more efficiently.
Hardware helps too. Special chips designed for inference can run the same maths faster and with less energy than general-purpose hardware. That is part of why phones can now run useful AI features without sending everything to the cloud.
There is also a design choice you feel directly: streaming. Instead of waiting for the whole answer, you see it appear word by word. Streaming does not make the total job faster, but it feels faster, and it lets you stop early if the answer is going the wrong way.
If you want to go deeper, IBM’s explainer on AI inference and Google Cloud’s guide to what AI inference is and how it works both walk through training versus inference with real-product examples.
Frequently Asked Questions
Is inference the same as using AI?
In most everyday cases, yes. When you ask a chatbot a question, upload a photo for tagging, or use voice-to-text, you are triggering inference: a trained model producing an output from your new input.
Does a model learn from my questions during inference?
Usually not. In a standard setup, the model’s weights stay fixed during inference, so your question does not retrain it on the spot. Some products may use aggregated feedback to improve future versions, but that is a separate training step.
Why is inference called the “doing” part of AI?
Because training is preparation and inference is performance. Training builds the model’s knowledge; inference puts that knowledge to work on real tasks, from answering questions to recognising objects.
Can inference run without the internet?
Sometimes, yes — if the model is small enough to live on your device. On-device inference powers features like offline translation and face unlock. Large chatbots usually need the cloud, because their models are too big to fit on a phone.
How can I get better answers from AI inference?
Be specific, give relevant context, and state the format you need. Then check important answers against a trusted source. A clear prompt helps the model pick the right pattern, but it does not guarantee correctness.
Conclusion
AI inference is simply a trained model doing its job: taking new input and turning it into an answer, a label, or a decision. Training gets the attention, but inference is what you actually experience — every search suggestion, caption, translation, and chatbot reply.
Try one practical step next time you use an AI feature: notice where it runs and how you check it. If it is a quick, low-stakes task, enjoy the speed. If it is a decision that matters, treat the output as a helpful draft and verify it before you act. That habit — use inference, then verify — will serve you better than any single tool or model.
Start there: pick one AI feature you use often, ask it a question you already know the answer to, and see how close it gets. You will learn more about inference from that one test than from any definition.